What you get.
Segal Intelligence
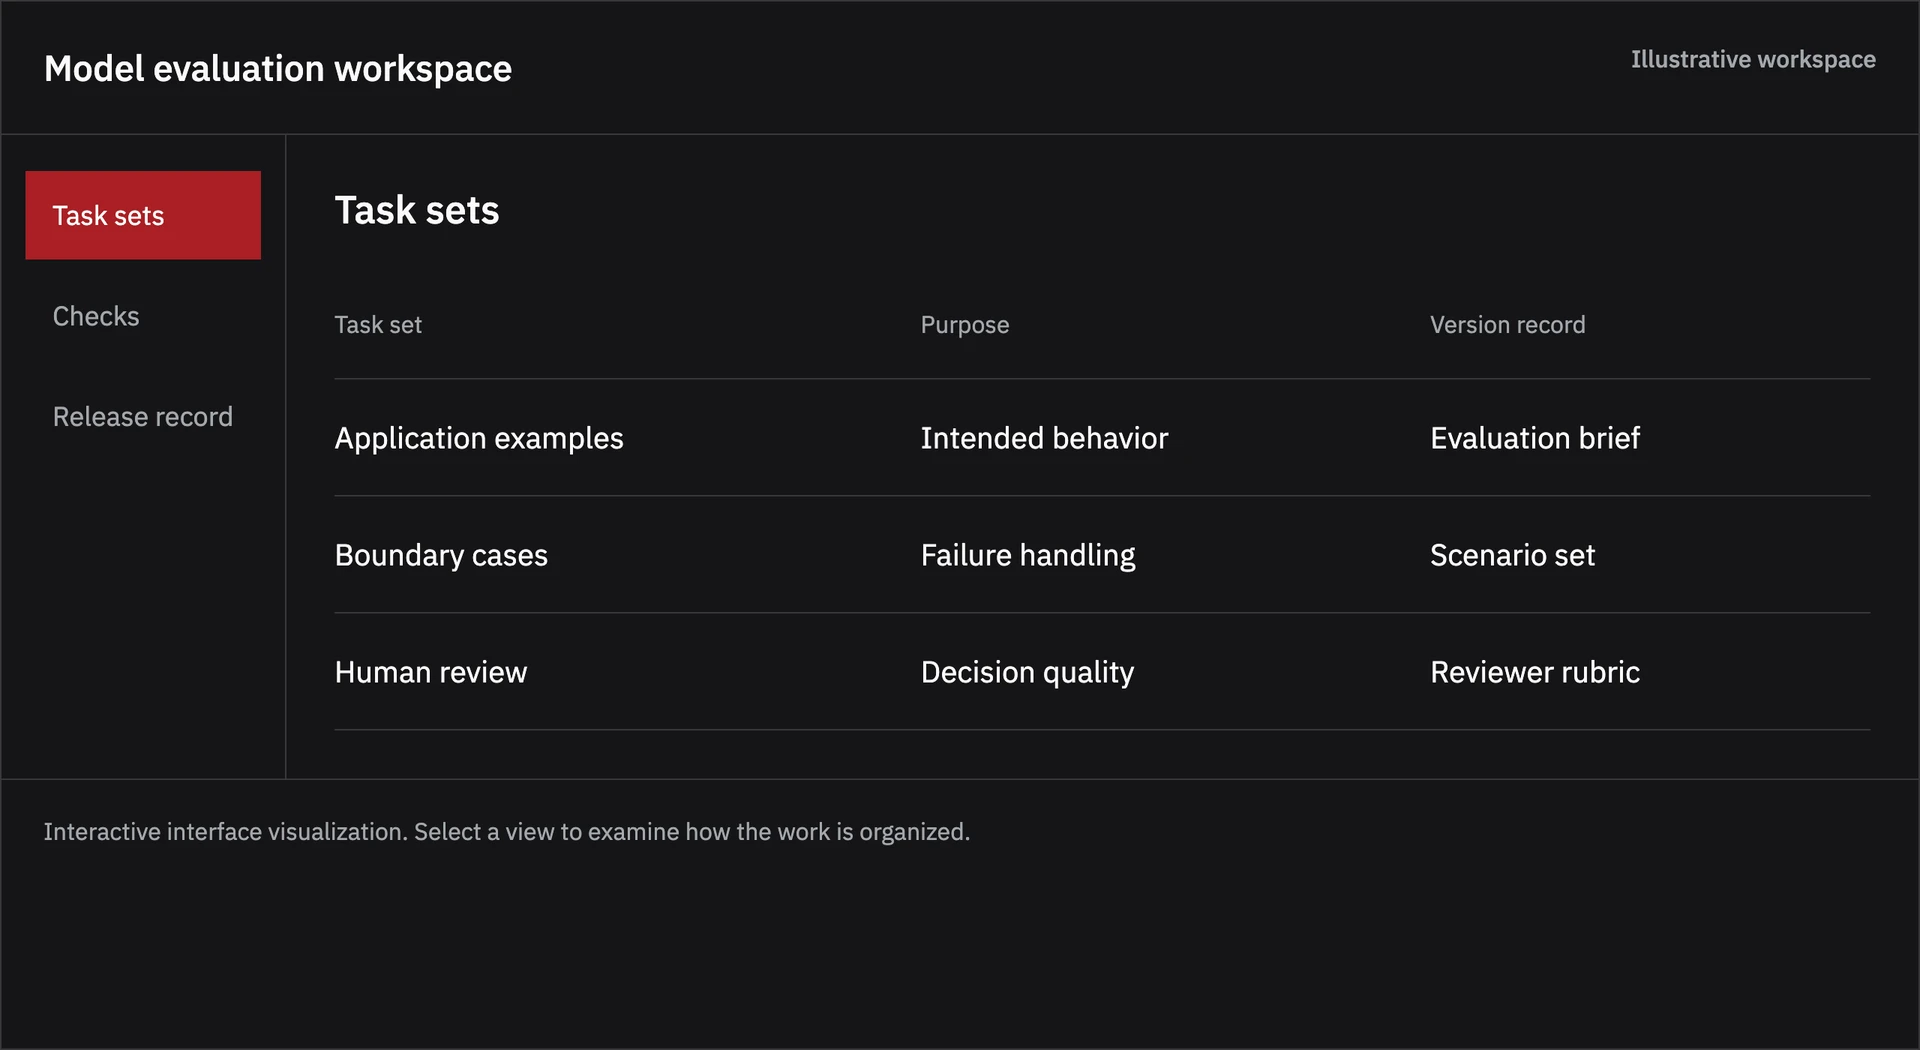
Model Evaluation builds evaluation sets, test environments, and review workflows around an AI system’s intended use. Tasks, sources, failure modes, and acceptance criteria are stated before a comparison or release decision. Results remain tied to the tested model version, data, and system configuration. A benchmark supports a measured application decision rather than becoming a universal performance guarantee.
Task
The intended use defines model and system requirements.
Evaluation
Versioned tasks and acceptance criteria support comparison.
Authority
Permissions, human review, and recovery define operation.
Focused application
Scope: One defined task family. Deployment: Application interface specified in discovery
Platform program
Scope: Coordinated task families. Deployment: Shared evaluation, tools, and deployment interfaces
In Intelligence
15 / 16
Build the frontier
with us.
Share the objective, the requirements, and the business you want to reach. Project and partnership enquiries all come through the same form.
Discuss a Project